Research ·
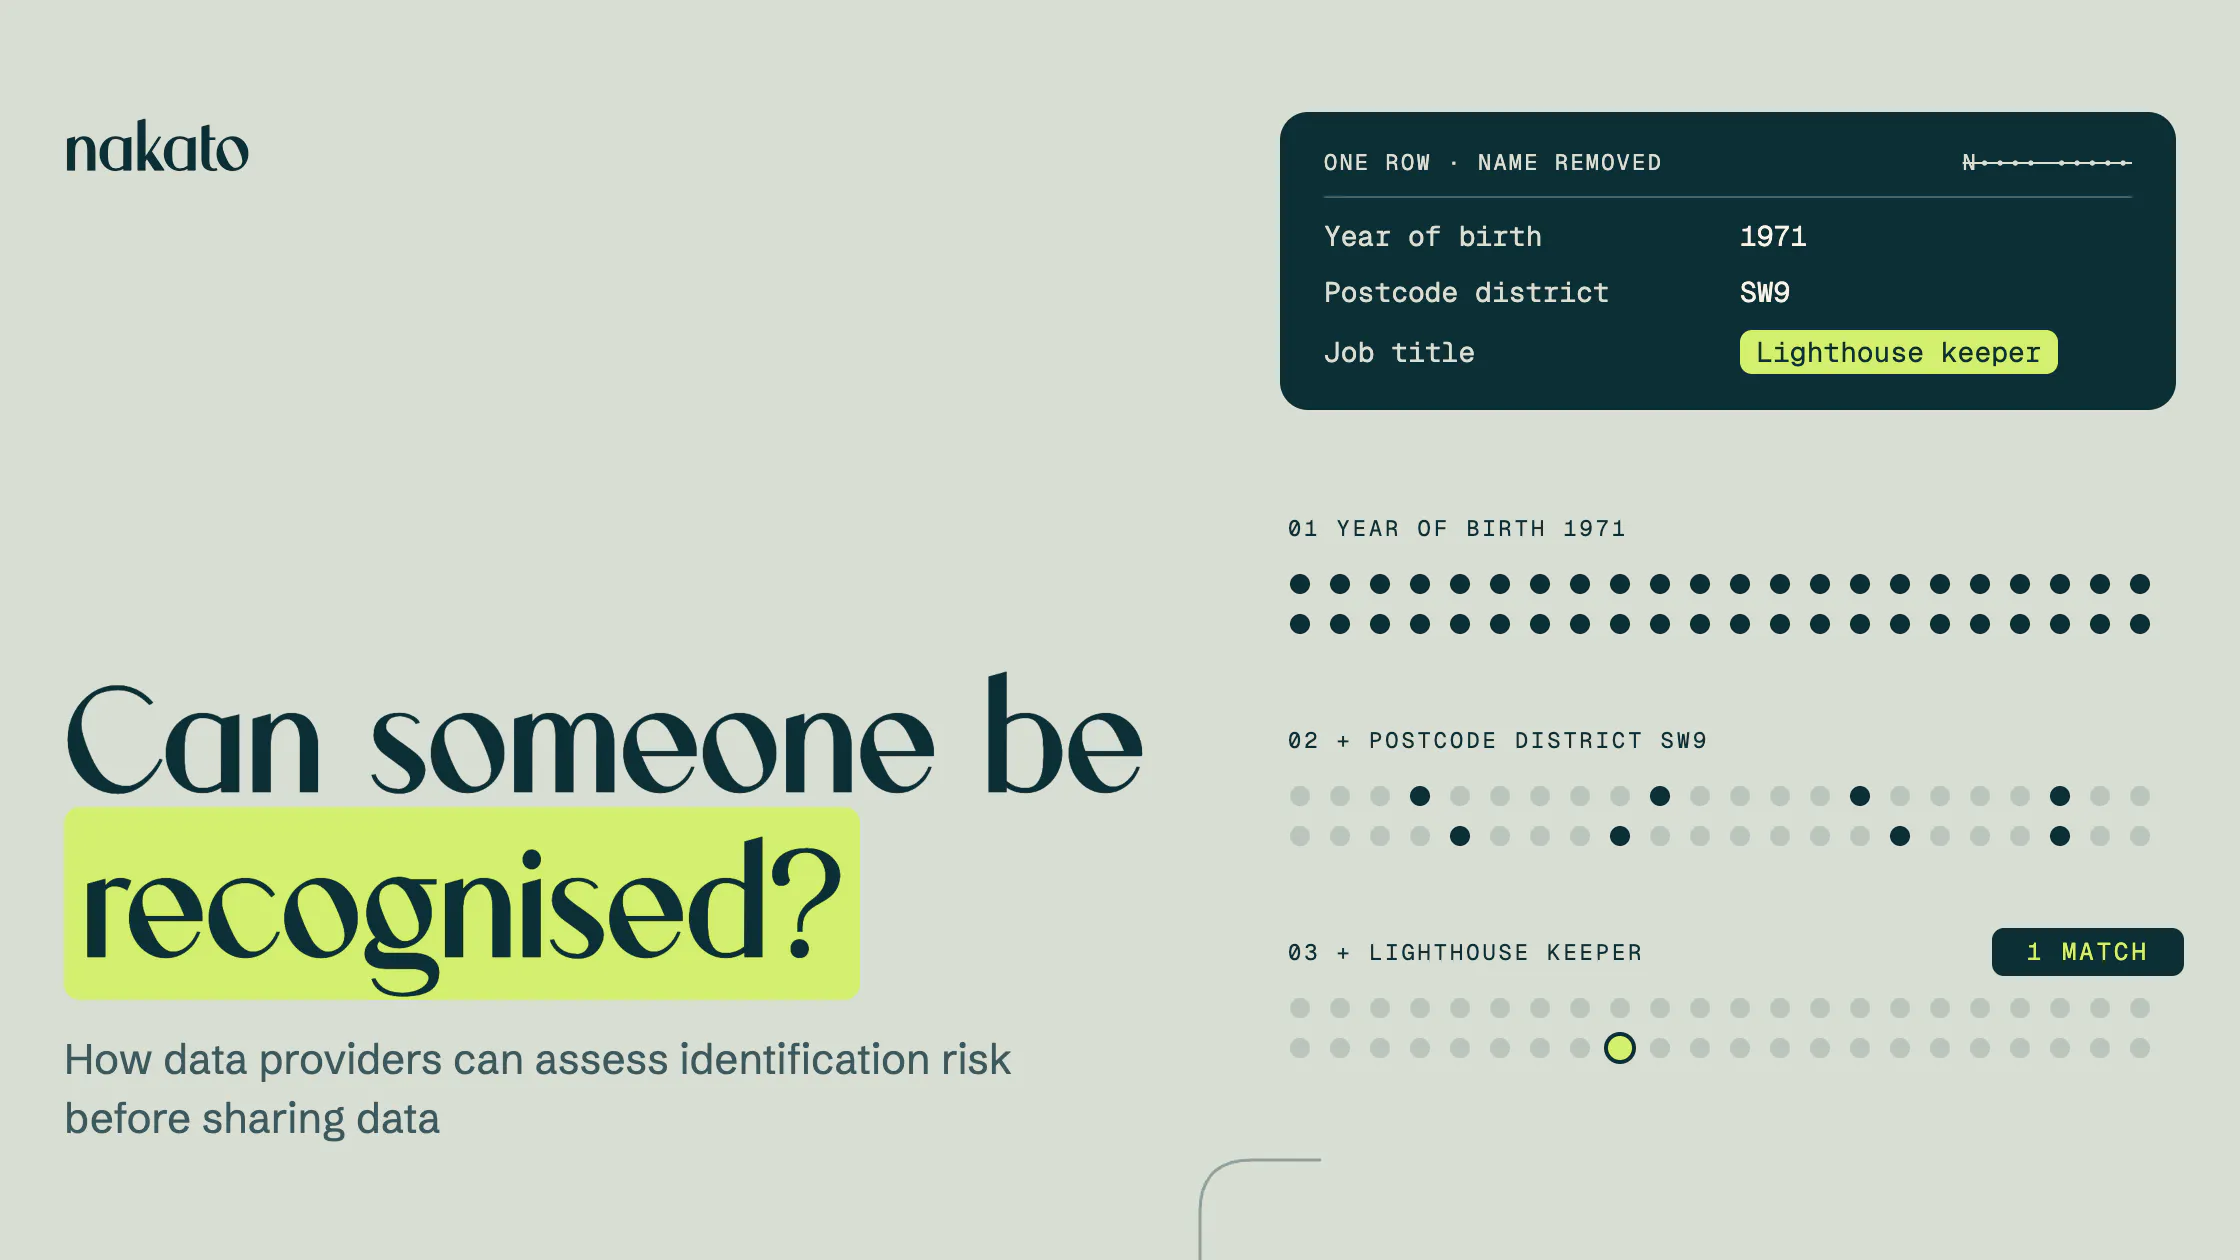
Can someone be recognised? How data providers can assess identification risk
Before you share record-level data, work out who will receive it and what they could match it against. Then choose your privacy tools.
By Nakato · 7 min read
Articles from the team: what a ruling means for sending data to an AI model, how a method holds up under test, and what we have built and why.
Research ·
Before you share record-level data, work out who will receive it and what they could match it against. Then choose your privacy tools.
By Nakato · 7 min read
Research ·
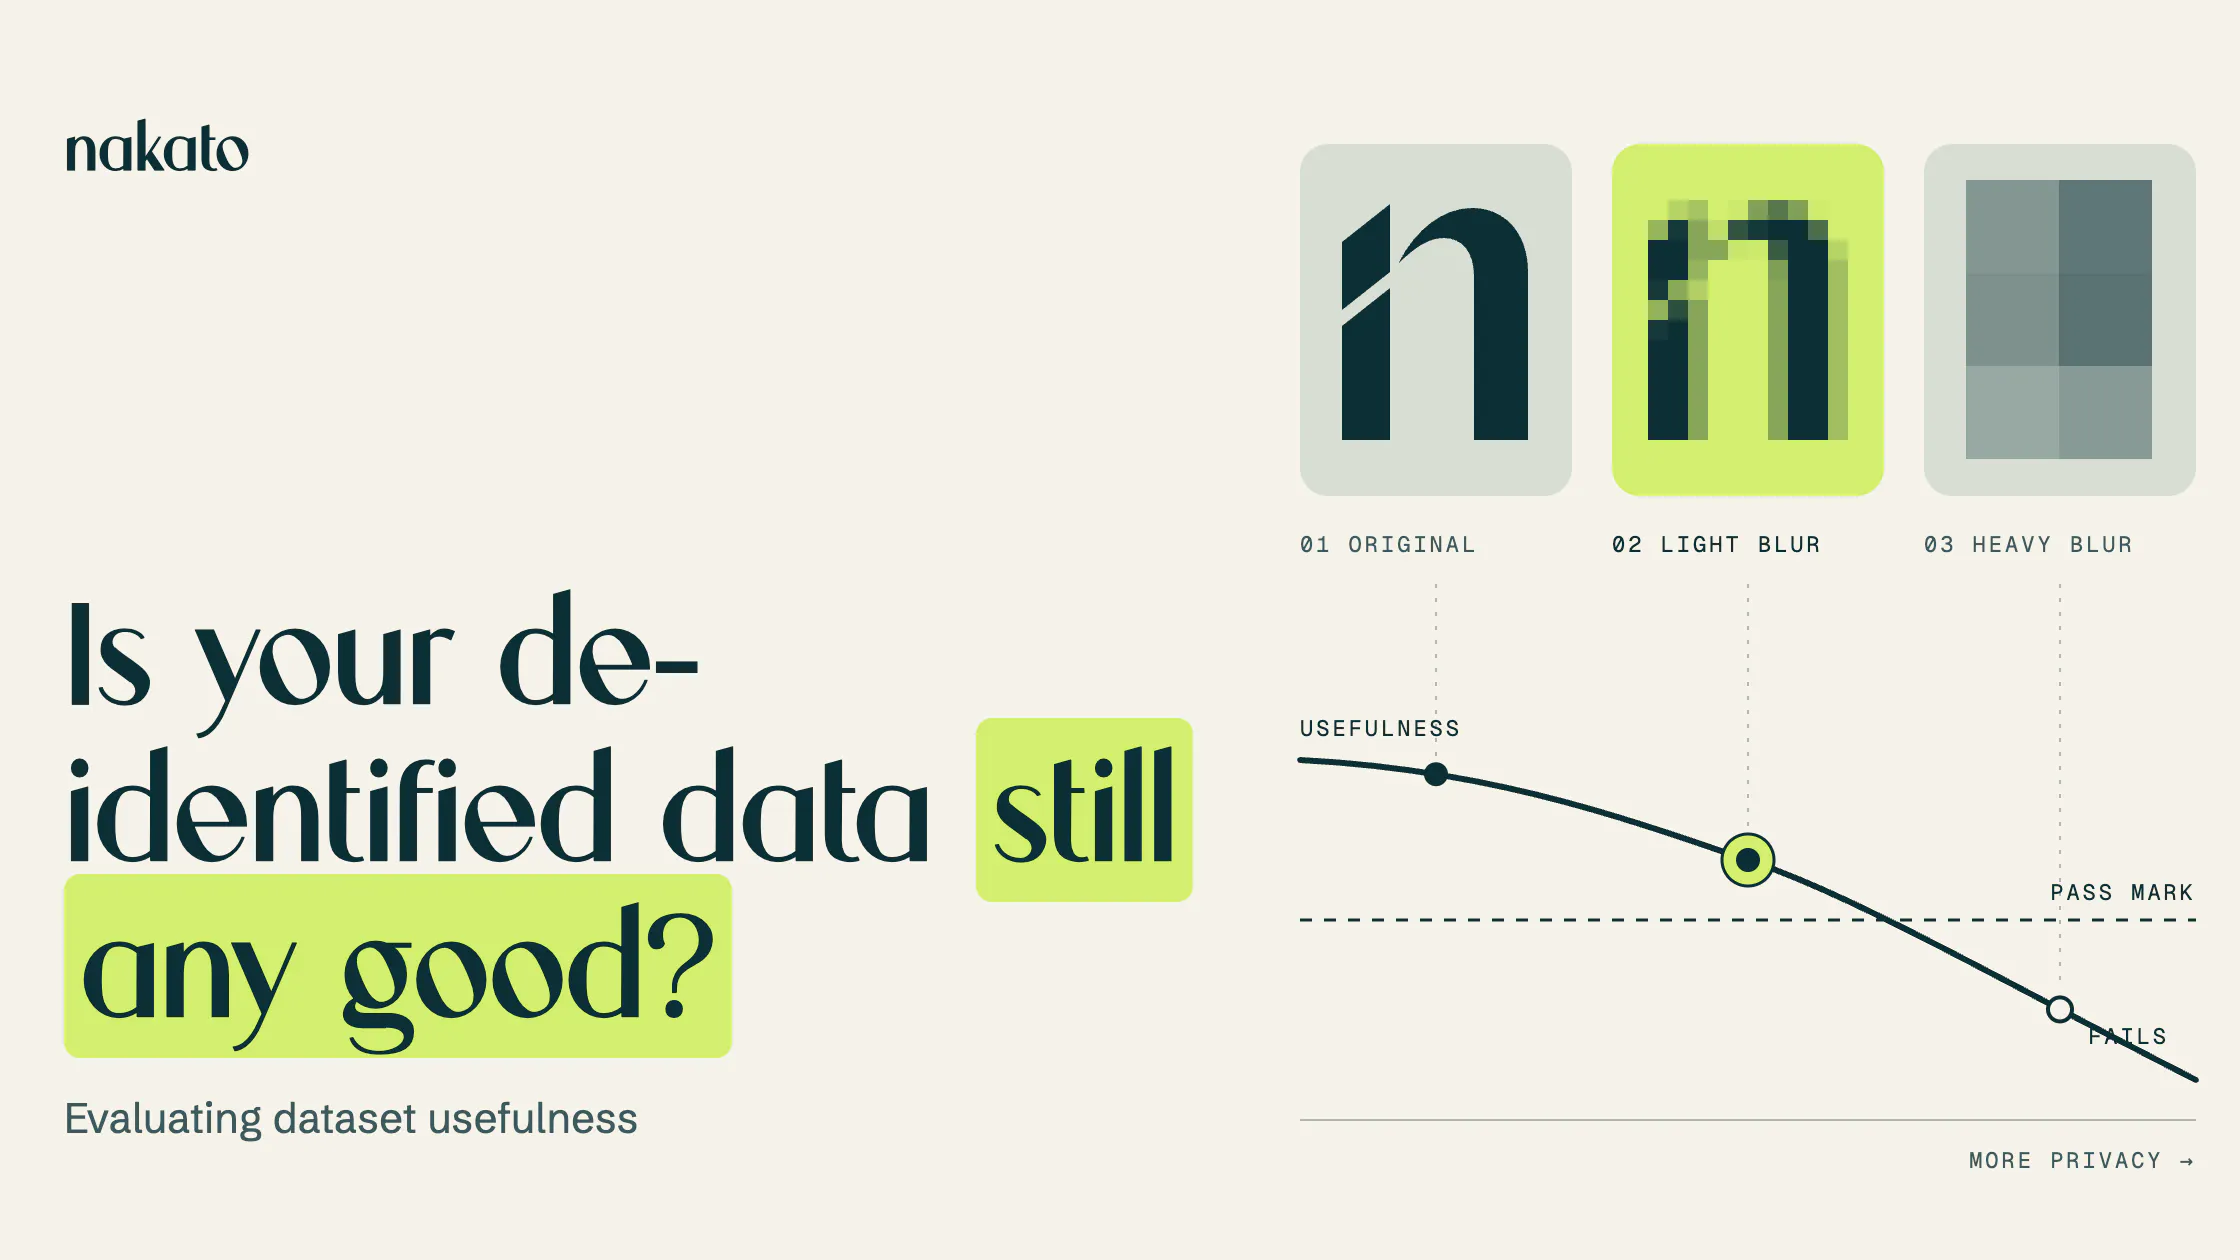
Run the same analyses on the de-identified copy and the original, then compare the answers – and check the privacy risk in the same review.
8 min read
Engineering ·
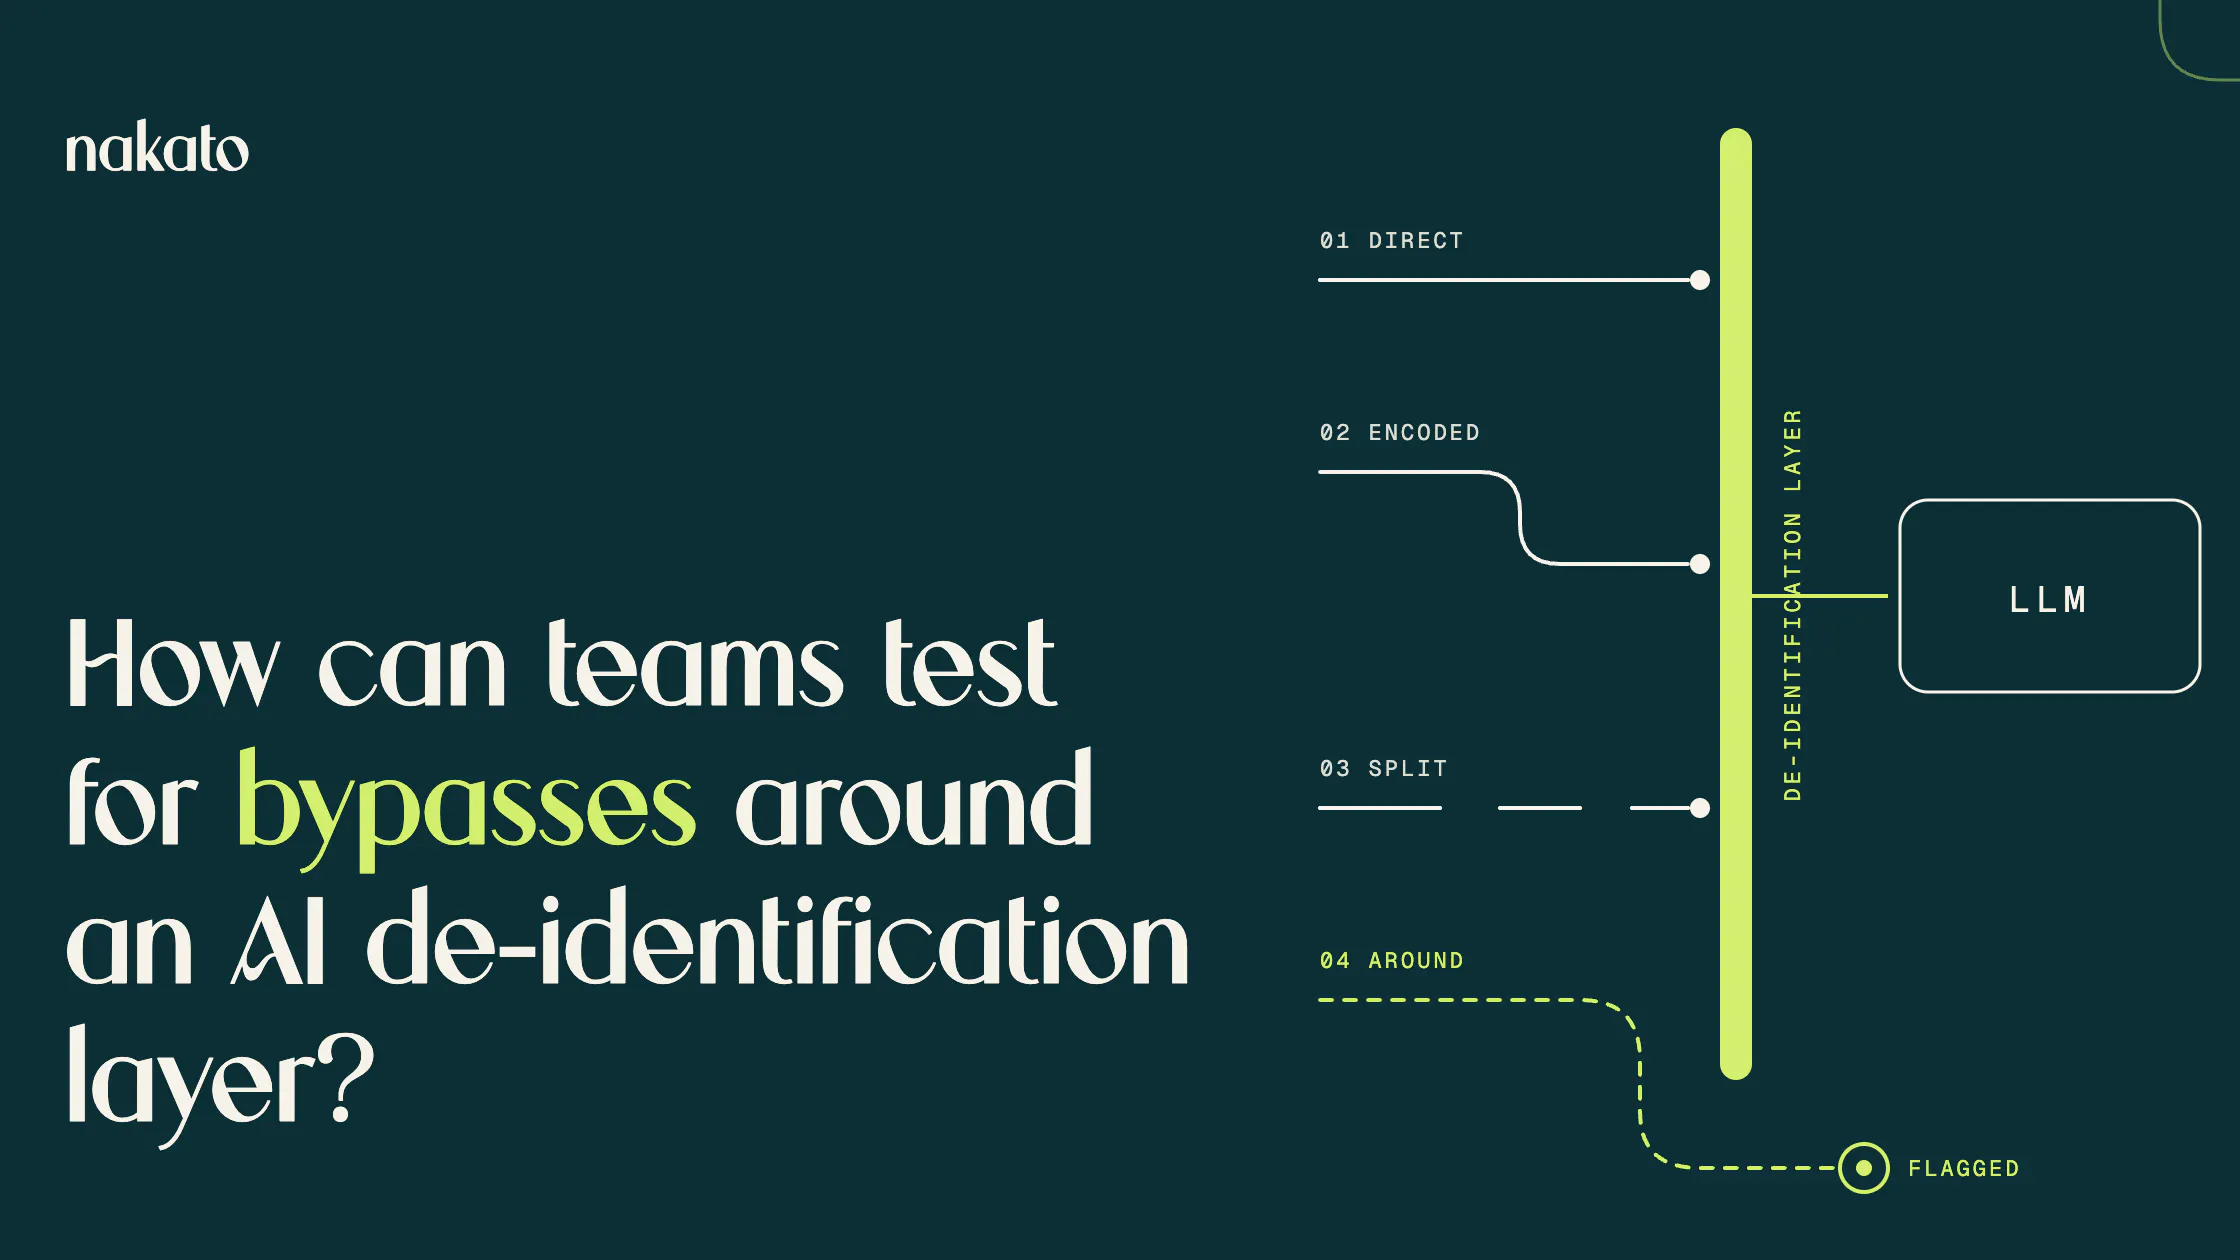
A de-identification layer protects only the traffic routed through it. Test every route a prompt can take, not just the detector.
5 min read
Regulation ·
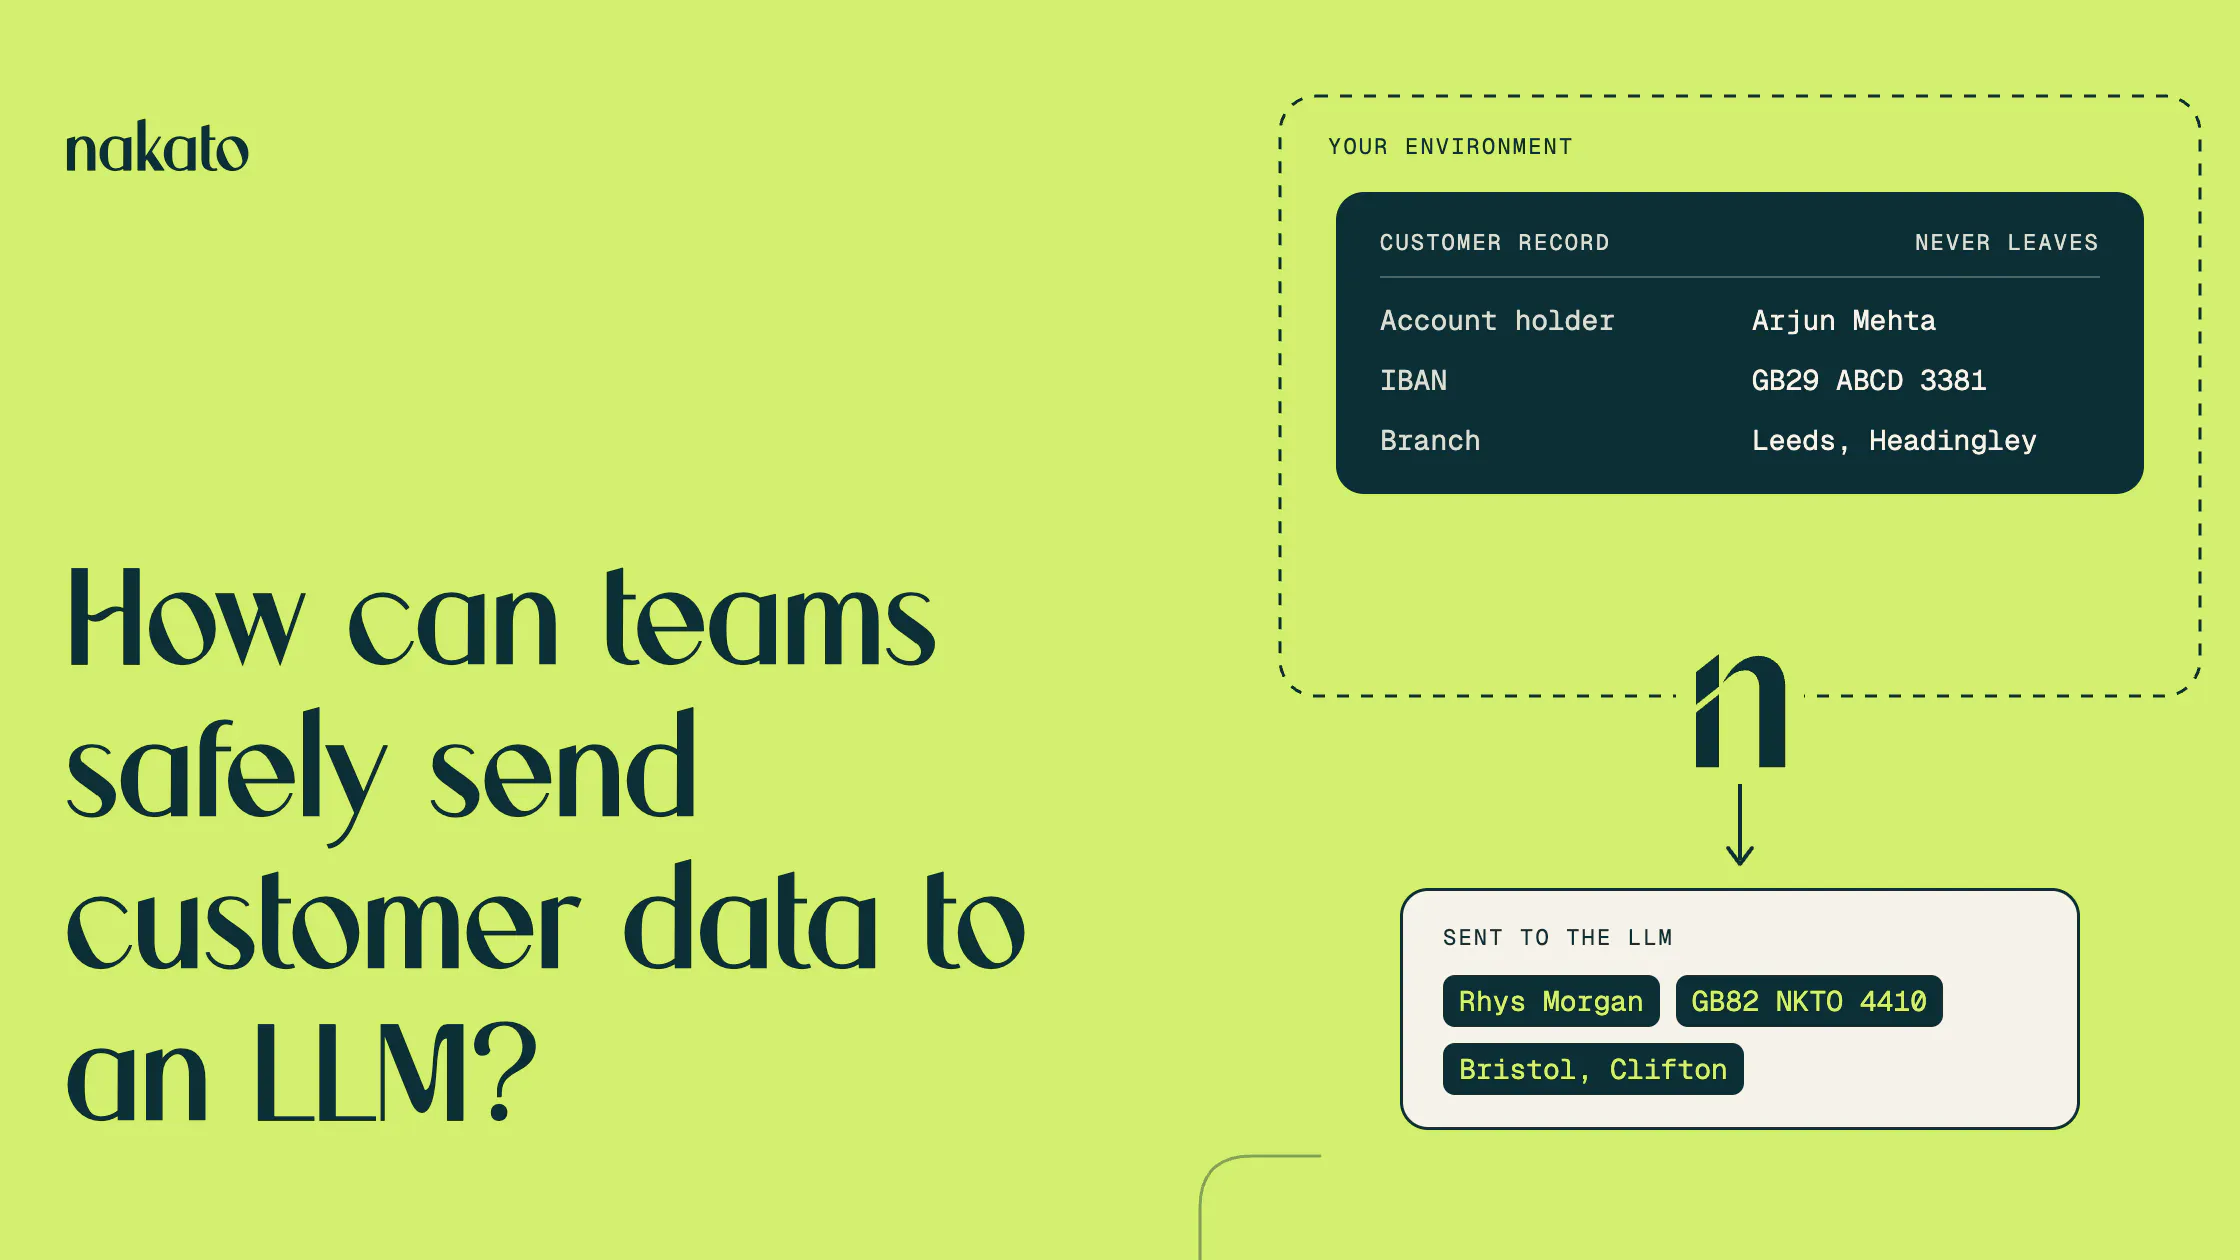
Approve one task and one data flow, keep the key that reverses the twins in your own environment, and test the detector on your own text.
7 min read
Regulation ·
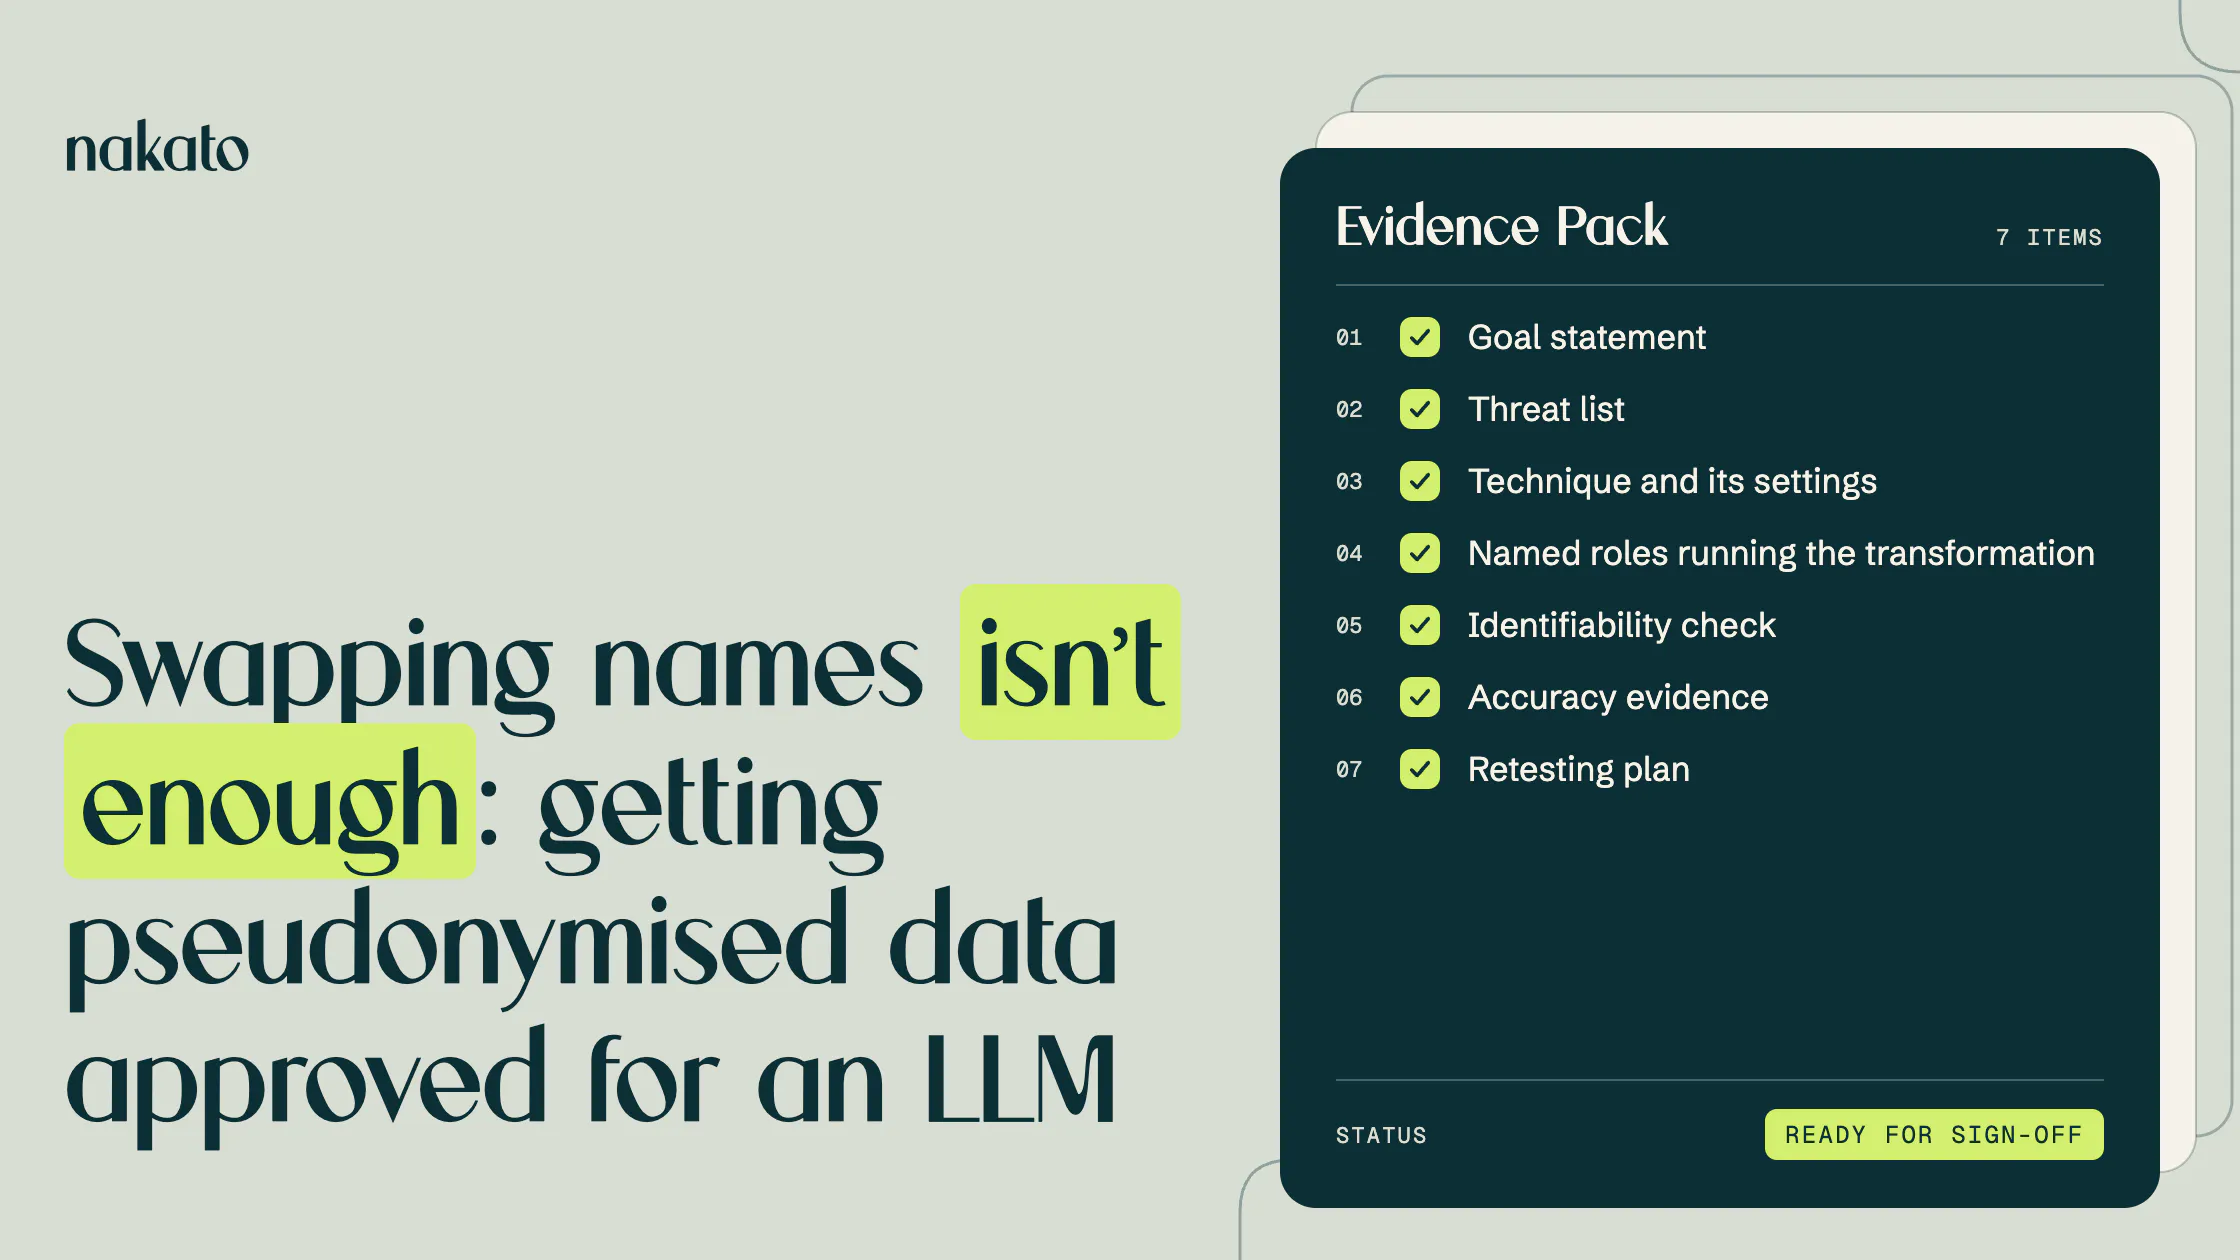
Pseudonymised data stays personal data while you hold the key. A committee approving it for an LLM needs written evidence on seven points.
6 min read
Research ·
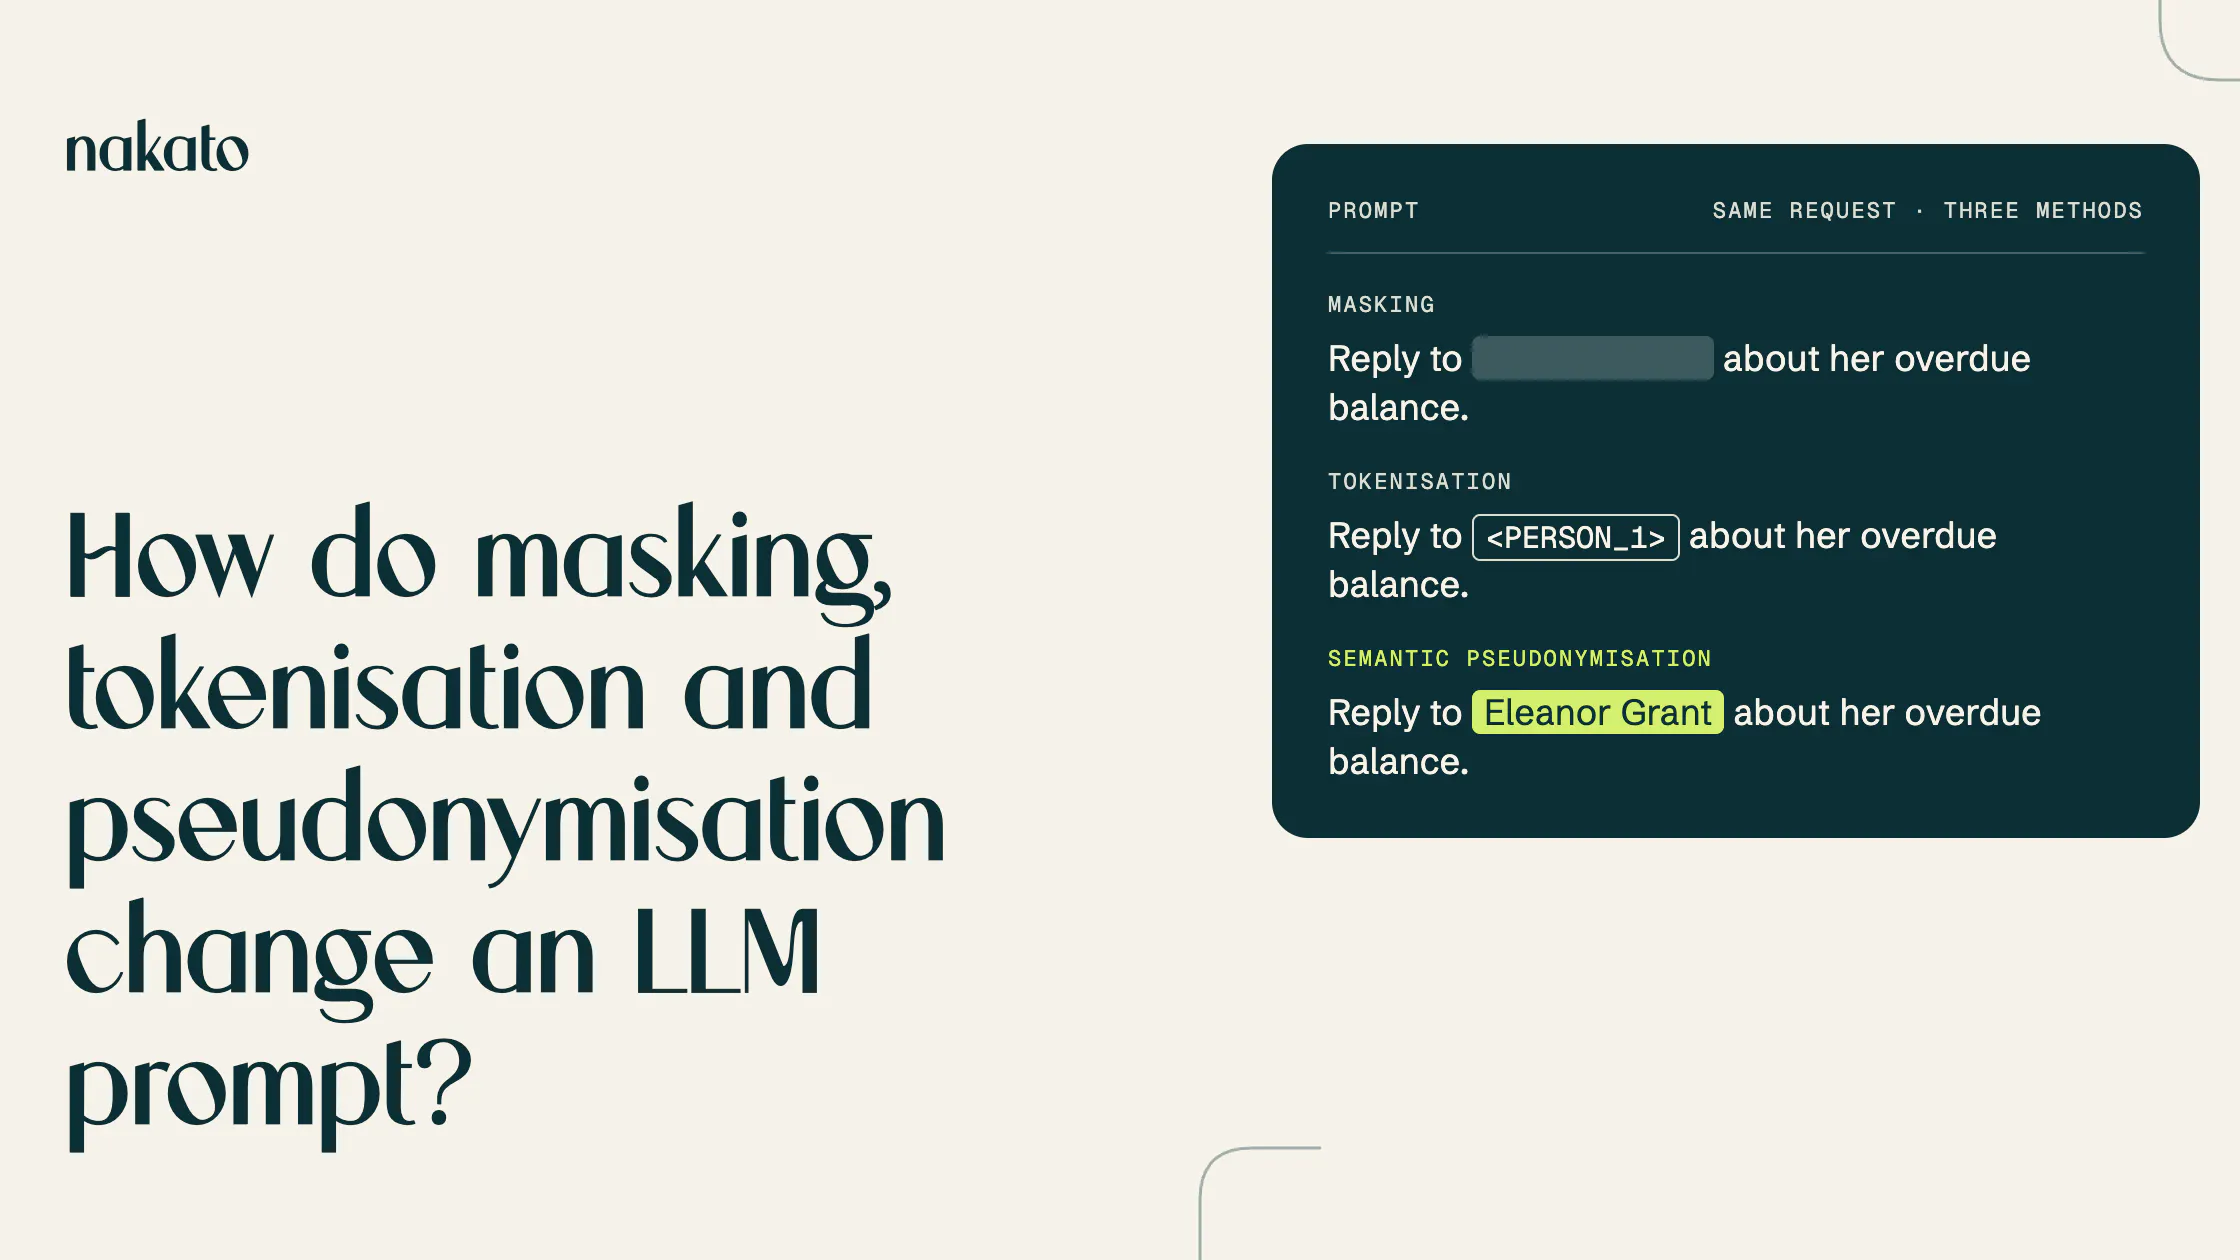
The right de-identification method depends on what the prompt needs.
6 min read
Research ·
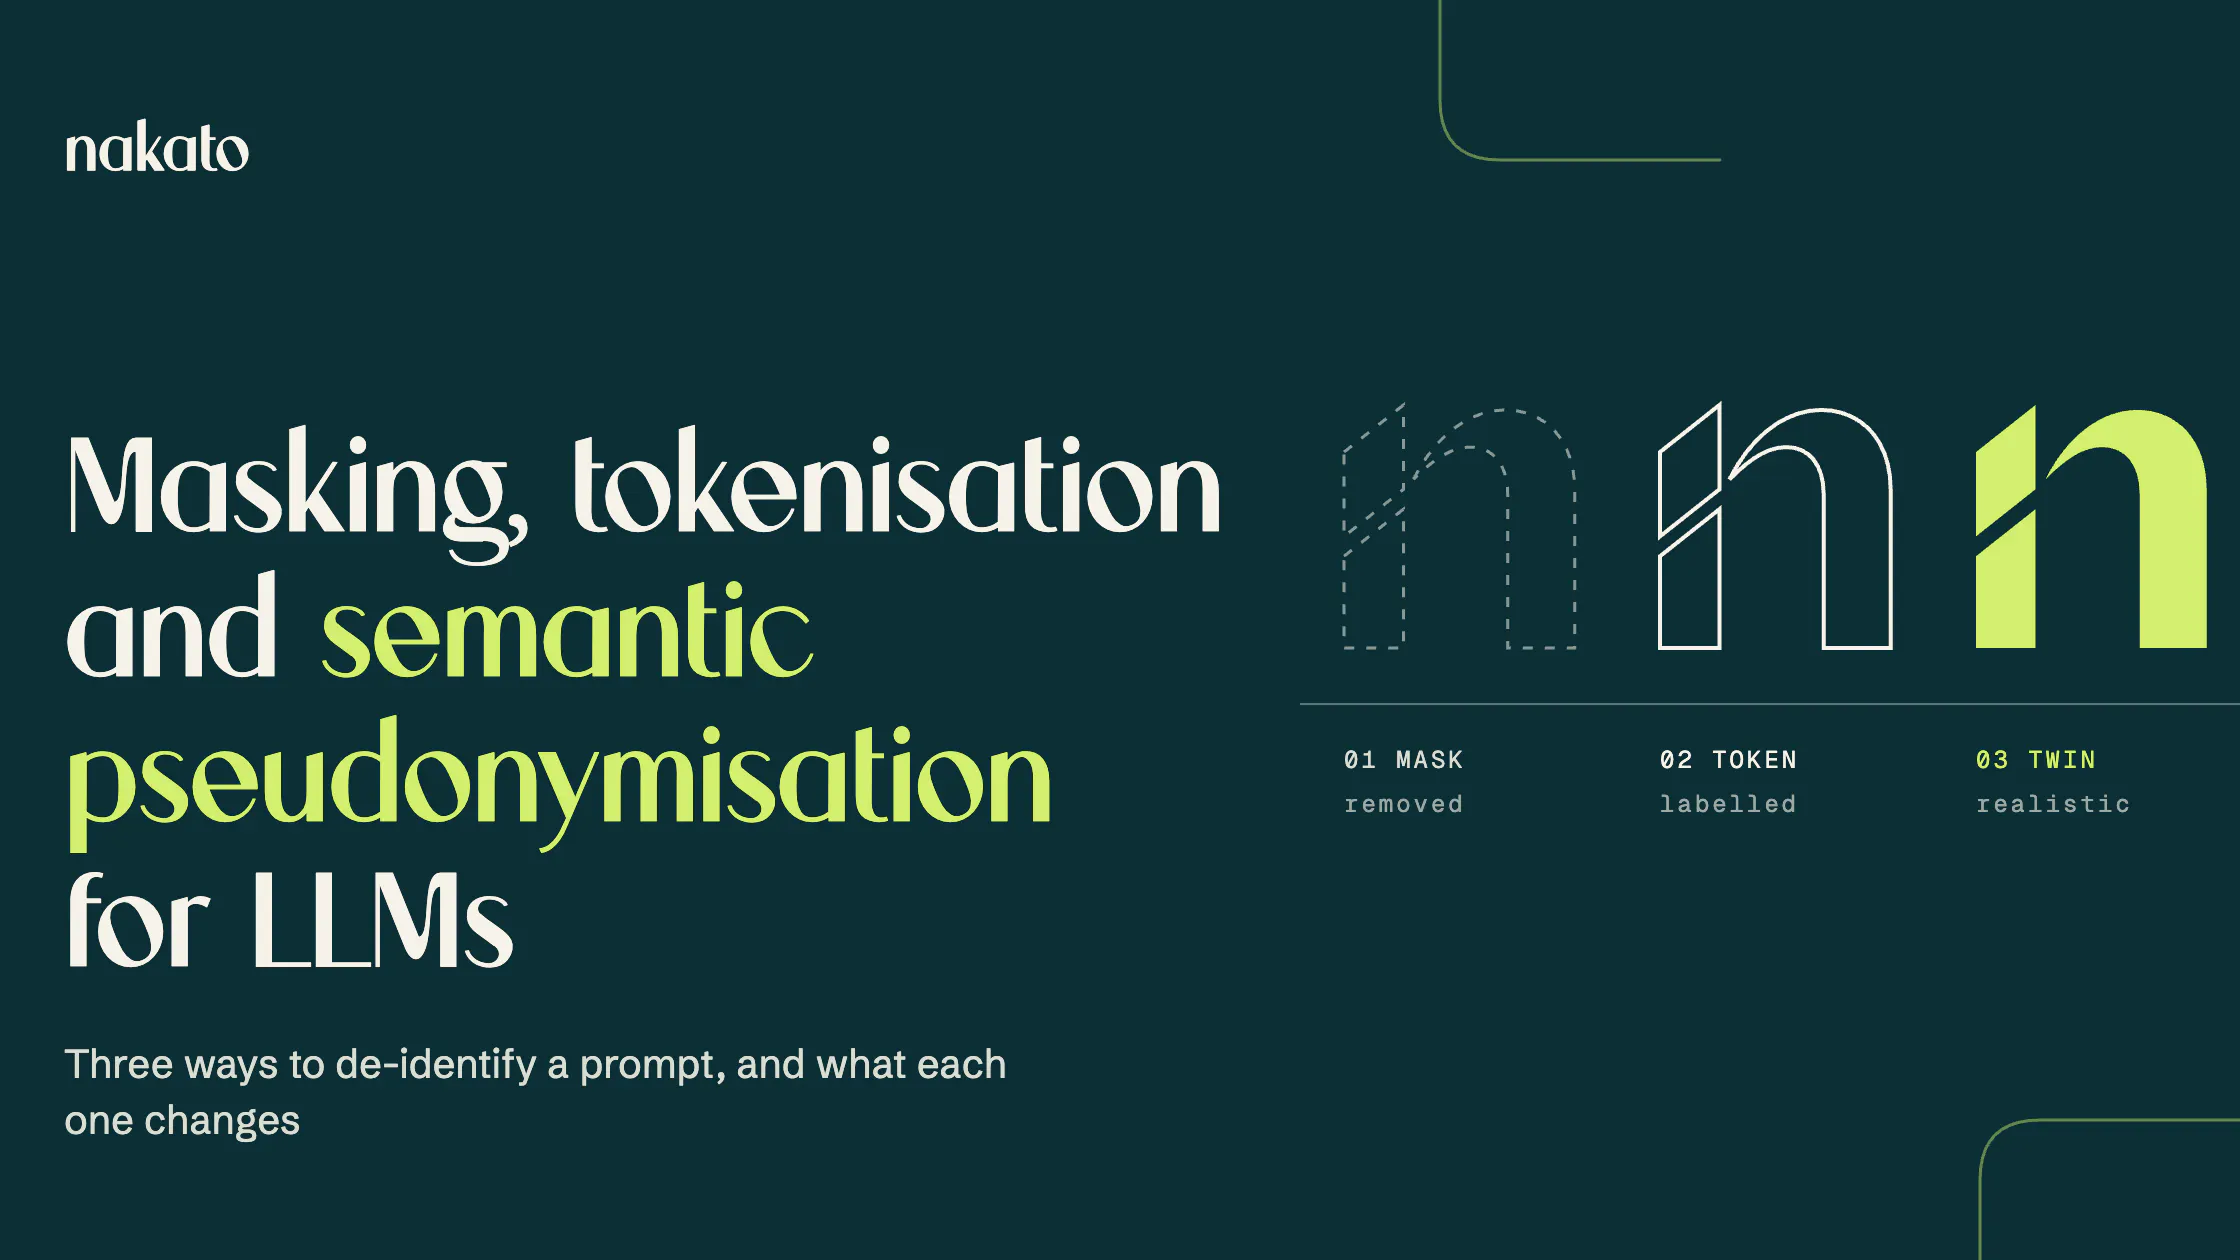
Masking deletes values, tokenisation swaps in labels and semantic pseudonymisation gives realistic stand-ins the model can still reason with.
9 min read